MICROBENCH: Preprocessing and QC record
Pipeline-internal steps described only briefly in the manuscript and expanded here with full detail: sequencing QC, classifier benchmarking, donor-derived custom Kraken2 database construction, BASEN method development, read-level compositional QC, and donor technical-replicate comparison.
1. Preprocessing
- Basecalling
- MinKNOW does not include the most recent Dorado basecaller.
- Using the POD5 files, we executed Dorado (v1.1.1) on high-performance computing clusters.
- Model used: dna_r10.4.1_e8.2_400bps_sup@v5.2.0
- A code set for reproducibility: Griffin-Pipeline tutorials
- Workflows
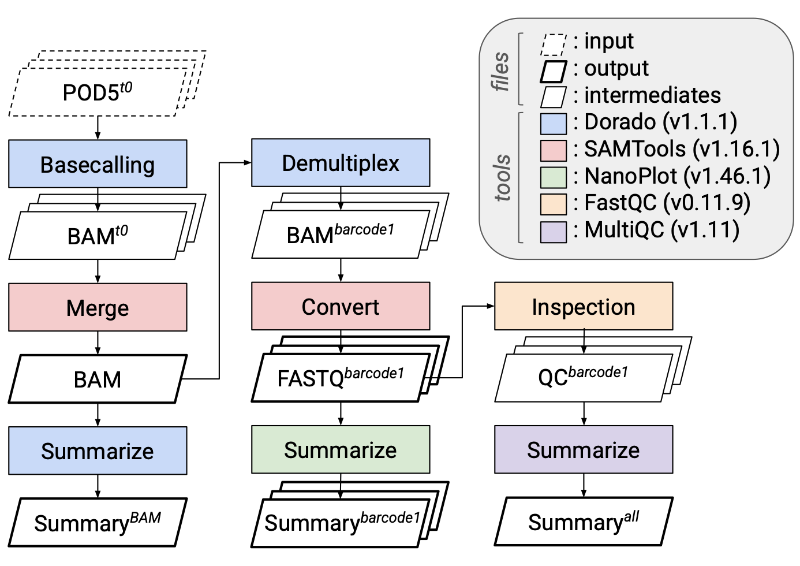
- Basecalling and demultiplex results
- Quality assessment
- Dorado Run Analyzer
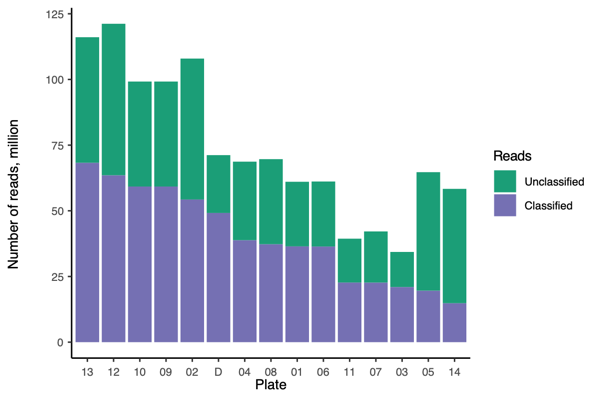
- Sequencing data summary: reads, quality, N50, etc.
- MultiQC results
- Detailed MultiQC results: (1) per plate, (2) per barcode, and (3) by read length, with reads triaged by length
- Study design
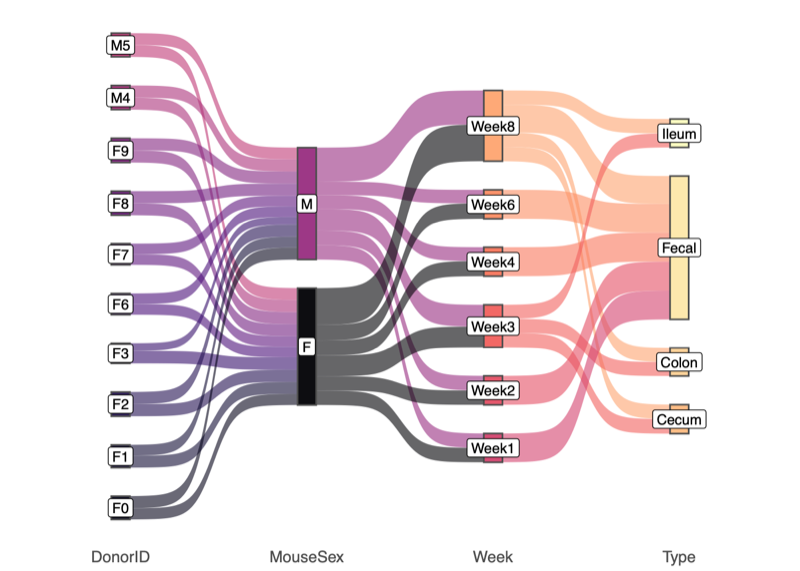
- Read quality control
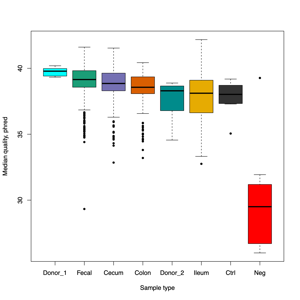
- MultiQC summary: per-base read quality
- Mini conclusion: Based on the MultiQC summary above, we applied length-based read filtering as follows:
- Short reads were retained; reads shorter than the Kraken2 k-mer length (35 bp) yield no k-mers and remain unclassified
- Long reads were trimmed to 14,999 bp
- Ultra-long reads (>100,000 bp) were discarded
- Read length and quality by donor and sample type
- Read length and quality per donor
- Read length and quality per sample type
- Sample-level QC after read filtering
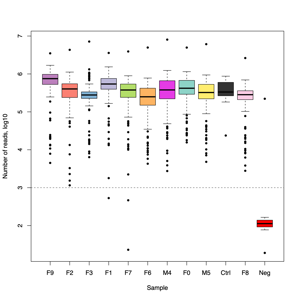
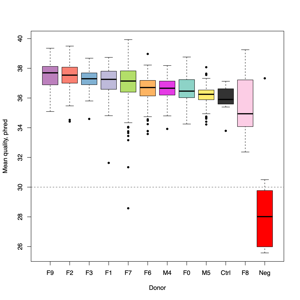
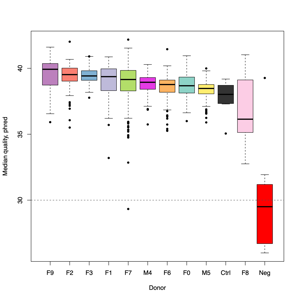
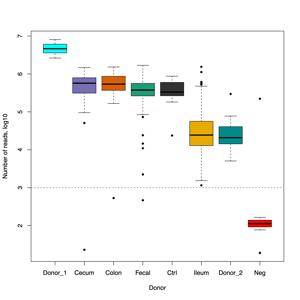
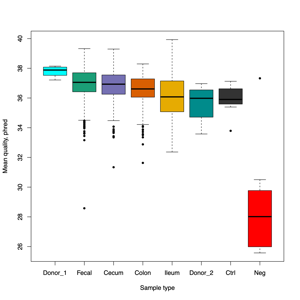
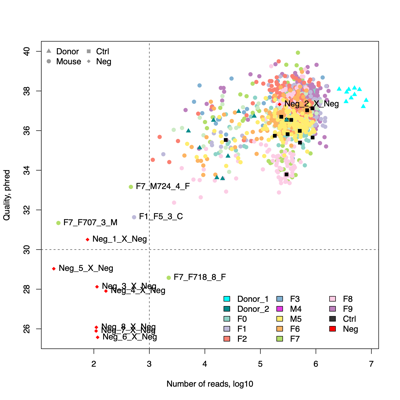
- FASTQ stats: number of reads and mean/SD/median quality
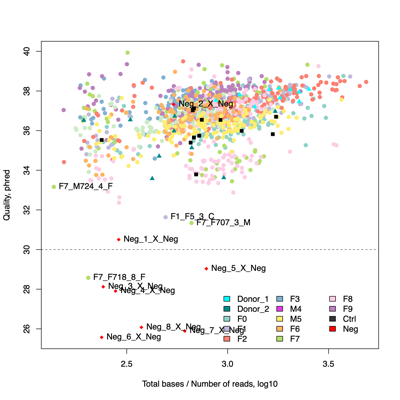
- Read length and quality: four mouse samples with fewer than 1,000 reads or a quality score below 30 (dashed lines) were excluded, together with the negative controls
- Summary
- Barcodes sequenced: 1,299
- Barcodes with reads: 1,278 (21 barcodes yielded zero reads)
- Samples passing read quality: 1,249 (29 barcodes excluded for poor read quality)
- Analysis-ready samples: 1,237 (8 negative controls and 4 low-quality mouse samples excluded)
- Mouse samples, N=1,206
- Donor samples, N=10
- Donor replicates, N=9
- OMM12 controls, N=12
| Number of reads | Mean quality | Median quality |
|---|---|---|
 |
 |
 |
| Number of reads | Mean quality | Median quality |
|---|---|---|
 |
 |
 |
| Number of reads and Quality | Ave. read length and Quality |
|---|---|
 |
 |
2. Custom Database Generation
- Host read removal
- Input: the 1,237 analysis-ready samples
- Reads were aligned with minimap2 (v2.30) to the combined GENCODE primary assemblies of mouse (GRCm39) and human (GRCh38); reads with a primary alignment to either genome were discarded and unmapped reads were kept with SAMtools (v1.16.1)
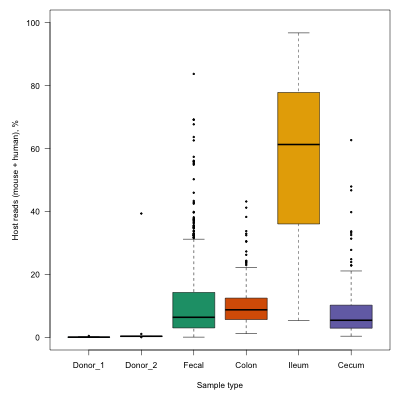
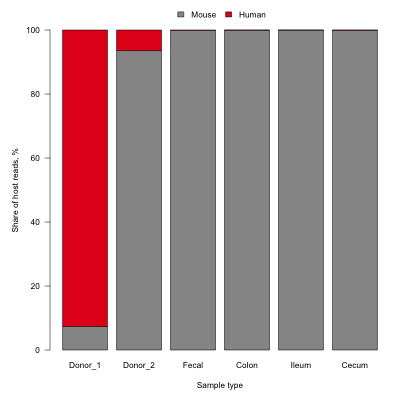
- Result: 575,225,291 reads → 62,664,009 mouse (10.9%) and 106,074 human (0.02%) reads removed → 512,455,208 host-free reads (89.1%)
- Host removal stats: total, mouse, human and host-free reads per sample
- Assembly and polishing
- Input: host-free reads of the 10 high-depth donor samples sequenced on the Donors plate (*_NA_0_1)
- Workflows
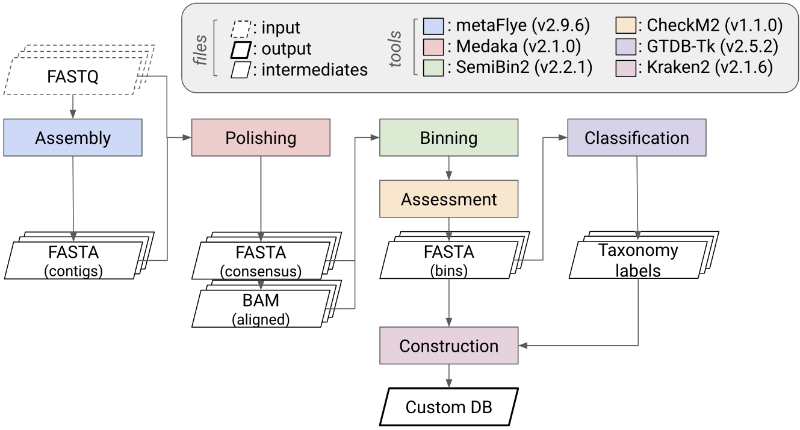
- Because long-read metagenome assembly and binning are not deterministic, the full assembly-to-binning workflow was run five times independently per donor (50 runs), and only species recovered reproducibly were kept (D. Pooling)
- Assembly: metaFlye (v2.9.6); polishing: Medaka (v2.1.0, model
r1041_e82_400bps_sup_v5.2.0, matching the basecalling model) - Binning and quality assessment
- Binning: SemiBin2 (v2.2.1), with contig coverage from the Medaka read alignments
- Quality: CheckM2 (v1.1.0); bins with completeness ≥90% and contamination <5% were classed as high quality, using the completeness and contamination thresholds of the MIMAG high-quality draft standard (Bowers et al. 2017); rRNA and tRNA gene content was not assessed
- Result: 7,627 bins → 1,979 high-quality bins across the 50 runs
- Pass rate: 25.9% of bins were high quality (1,979 of 7,627)
- High-quality bins per run: median 36, range 23–63
- Run-to-run stability: within a donor, the high-quality count varies by only 2–5 bins across the five runs (e.g. F2 35–37, F1 23–28)
- Pooling
- Within each donor, high-quality bins from the five runs were compared pairwise with skani (v0.3.1) and linked into species groups at ANI ≥95% (the operational species boundary; Jain et al. 2018), single linkage, no aligned-fraction minimum
- A species group was kept if it was recovered in at least three of the five runs; its representative was the bin with the highest completeness − 5 × contamination (dRep genome score; Olm et al. 2017)
- Result: 450 species groups → 397 per-donor representatives
- Run recovery: of the 397 kept groups, 335 were found in all 5 runs, 41 in 4 and 21 in 3; the 53 dropped groups were found in 2 runs (24) or 1 run (29)
- No duplicates within a run: no kept species group held two bins from the same run, so each run contributed at most one bin per species
- Taxonomic classification
- The 397 per-donor representatives (393 bacterial, 4 archaeal) were classified with GTDB-Tk (v2.5.2) against GTDB release 226
- GTDB-Tk results: classification, closest reference genome, ANI and aligned fraction per representative
- Dereplication
- Representatives from all donors were grouped across donors with the same rule (skani ANI ≥95%, single linkage): 191 cross-donor groups
- Single linkage can join closely related species, so groups holding more than one GTDB-Tk species were split by species: Phocaeicola dorei / P. vulgatus, and Prevotella copri_B / copri_G / copri_K
- Within each resulting unit the representative was again the genome with the highest completeness − 5 × contamination: 194 MAGs, one per species (five assigned to genus level only)
- Sharing: 82 of the 194 MAGs were recovered from two or more donors; the other 112 came from a single donor
- Database construction
- A custom Kraken2 (v2.1.6) database was built from the 194 MAGs, each assigned the taxonomic identifier of its GTDB-Tk species within a taxonomy built from the GTDB release 226 lineages (the five MAGs without a species-level assignment were given their own species node under their genus)
- Parameters: k-mer length 35, minimizer length 31, default low-complexity masking
- Database: 194 species, 3,233 contigs, 536,180,842 bp
- MAG list, N=194: GTDB name and lineage, donors, representative, completeness, contamination, contigs and size
- Summary
- 10 donors × 5 runs → 7,627 bins → 1,979 high-quality bins → 397 per-donor representatives → 191 cross-donor groups → 194 MAGs
| Host reads (mouse + human) per sample type | Mouse vs human share of host reads |
|---|---|
 |
 |
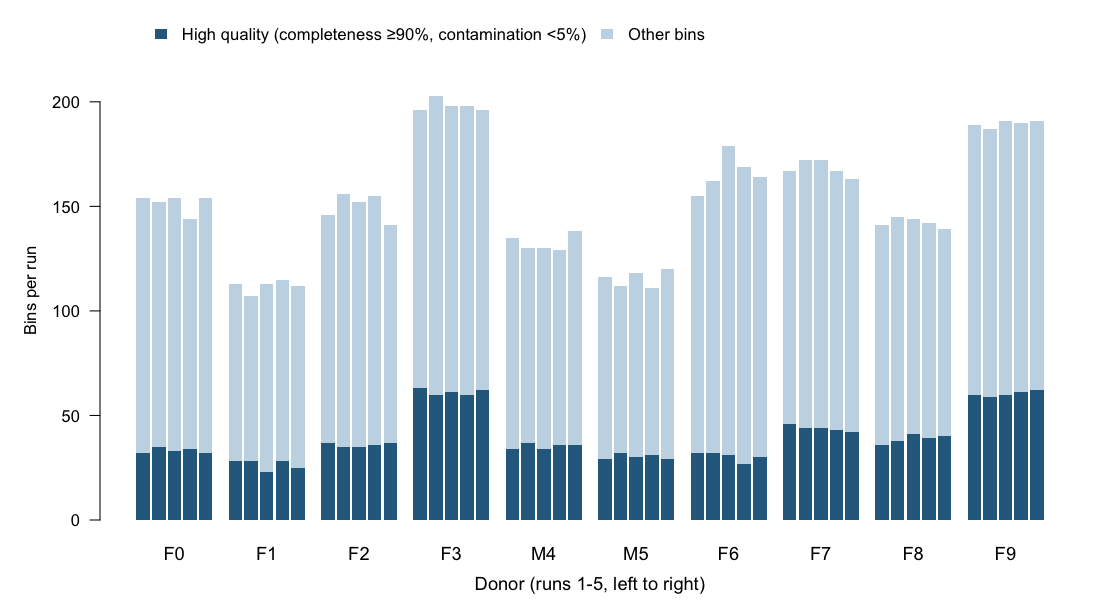
SemiBin2 bins per run, grouped by donor (runs 1–5, left to right); the dark part of each bar is the high-quality bins.
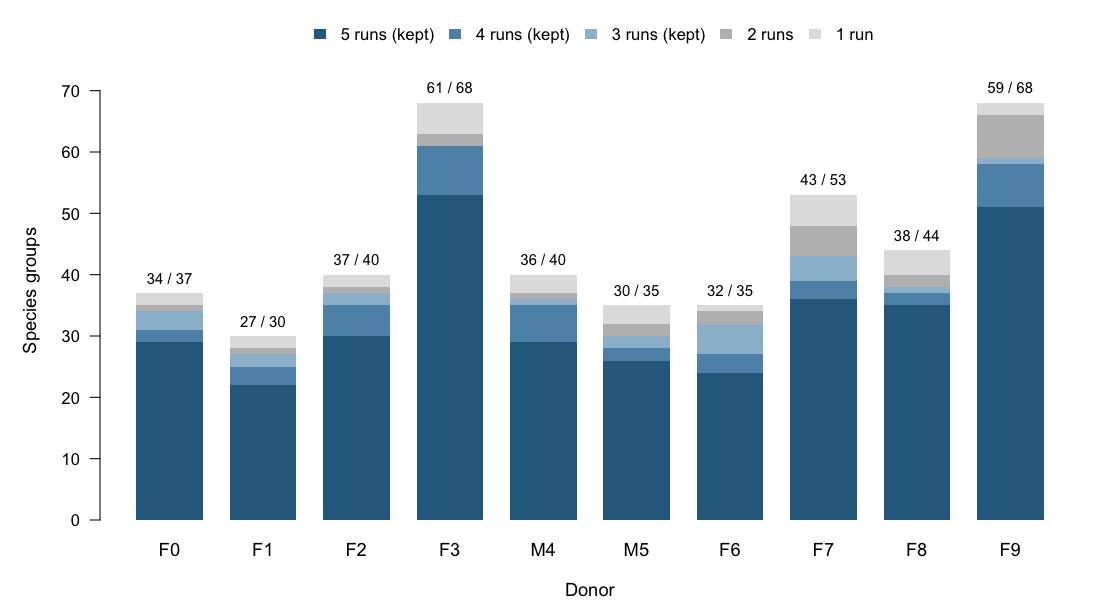
Species groups per donor after pooling the five runs, coloured by the number of runs in which each group was recovered; groups found in 3–5 runs were kept. Labels above the bars: kept / total groups.
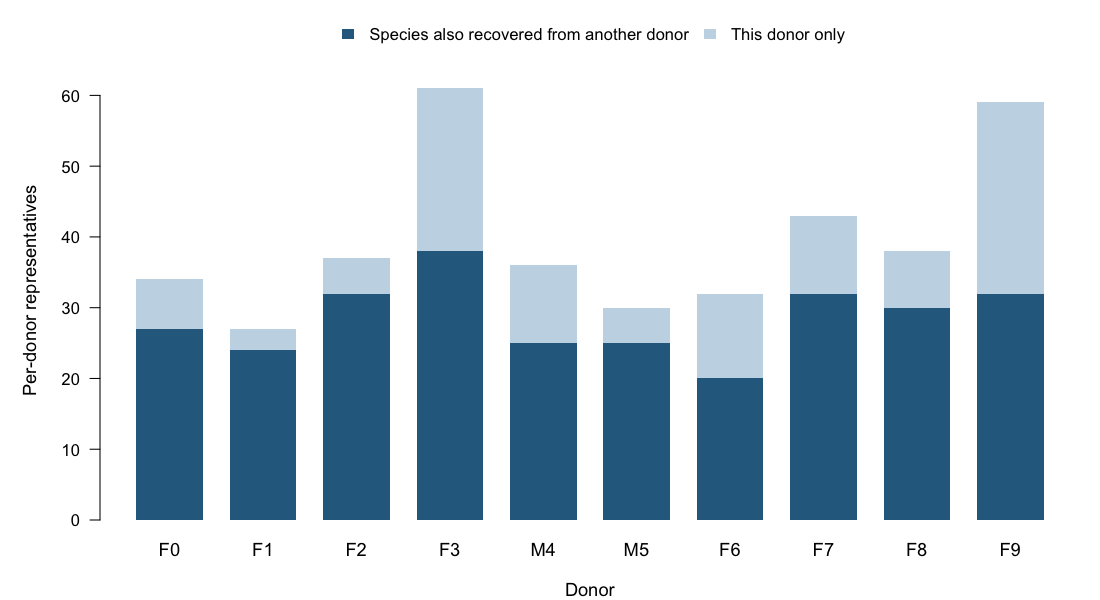
Per-donor representatives by donor, split by whether their species was also recovered from another donor.
| Donor | # Reads | # Host-free reads | # Contigs per run | # Bins | # HQ bins | # Species groups | # Kept |
|---|---|---|---|---|---|---|---|
| F0 | 4,963,485 | 4,940,900 | 13,805–13,852 | 758 | 166 | 37 | 34 |
| F1 | 3,581,456 | 3,574,599 | 7,510–7,562 | 560 | 132 | 30 | 27 |
| F2 | 4,325,290 | 4,323,065 | 11,699–11,791 | 750 | 180 | 40 | 37 |
| F3 | 7,151,869 | 7,143,120 | 18,628–18,722 | 991 | 306 | 68 | 61 |
| M4 | 8,050,964 | 8,049,152 | 11,013–11,128 | 662 | 177 | 40 | 36 |
| M5 | 6,104,905 | 6,102,896 | 9,244–9,282 | 577 | 151 | 35 | 30 |
| F6 | 4,970,540 | 4,967,193 | 11,304–11,353 | 829 | 152 | 35 | 32 |
| F7 | 3,914,021 | 3,909,053 | 11,685–11,747 | 841 | 219 | 53 | 43 |
| F8 | 2,626,645 | 2,625,582 | 11,555–11,621 | 711 | 194 | 44 | 38 |
| F9 | 3,497,575 | 3,494,727 | 14,448–14,526 | 948 | 302 | 68 | 59 |
| Total | 49,186,750 | 49,130,287 | 7,627 | 1,979 | 450 | 397 | |
3. Taxonomic Classification
- Taxonomy classification via Kraken2 with the custom DB (194 MAGs)
- Input, N=19
- Sequenced using 10 barcodes on a 96-well plate to achieve high(er) coverage (*_NA_0_1), N=10
- Technical replicates of the donor samples were sequenced on the mouse plates (Plate01–14) with one barcode each, at much lower depth (5,059–296,580 reads vs 2.6–8.1 million) (*_NA_0_2), N=9 No replicate was sequenced for F1 (no F1_NA_0_2 in the study design)
- Reference database: the custom Kraken2 database of the 194 donor-derived MAGs (Section 2; GTDB r226 taxonomy)
- Taxonomy classification:
- Problem definitions:
- Raw read counts are not directly comparable across samples. Sequencing depth can vary substantially across sequencing runs, flow cells, and barcodes. For example, the ten high-depth donor samples alone contained approximately 2.6–8.0 million reads. Consequently, raw taxon counts are strongly influenced by total sequencing depth and do not provide a normalized measure of abundance across samples.
- The proportion of reads classified by Kraken2 also varies among samples. Among the high-depth donor samples, the classified fraction ranged from 73.1% to 88.3%. As a result, the proportion of total reads assigned to a given taxon is affected not only by its underlying abundance, but also by sample-specific variation in classification efficiency. Thus, two samples with similar biological composition may exhibit different read proportions simply because different fractions of their reads were successfully classified.
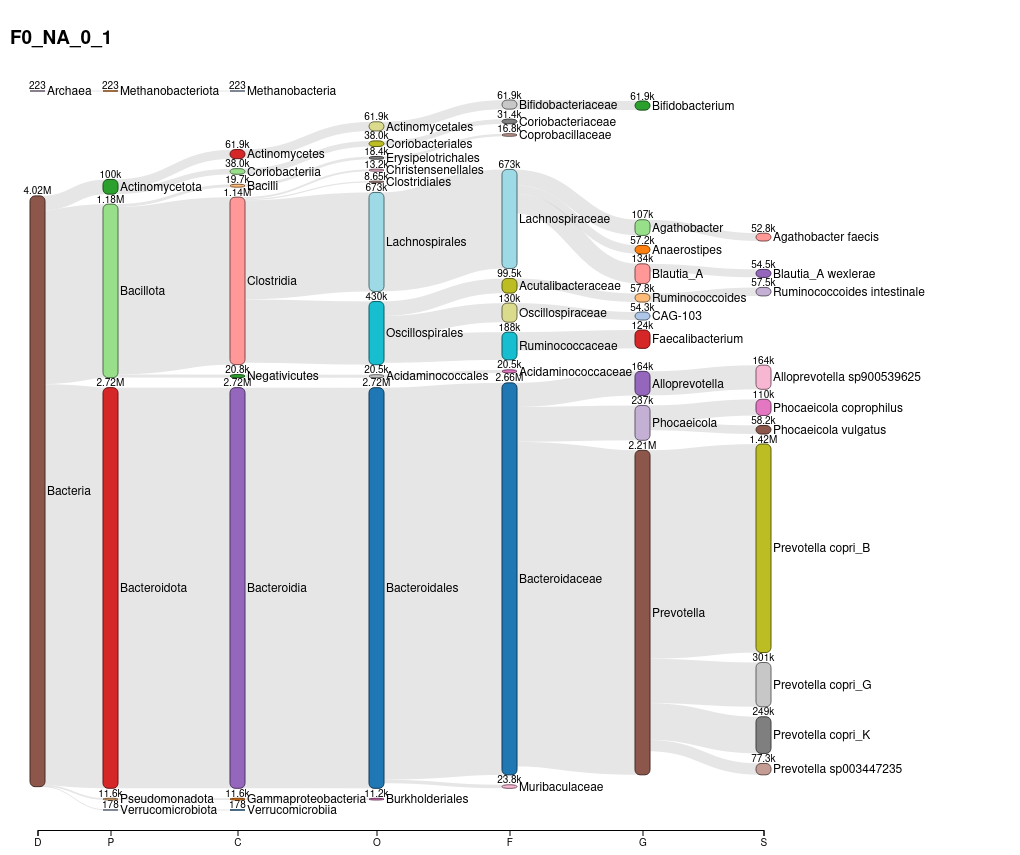
- Taxonomic assignments are distributed across multiple ranks and are therefore not directly comparable. Kraken2 assigns each read to the lowest common ancestor (LCA) supported by its k-mer matches. Consequently, some reads cannot be resolved to the species level and are instead assigned to the genus or a higher taxonomic rank. For example, in sample F0_NA_0_1, 161,202 of the 2,206,146 reads associated with Prevotella were assigned above the species level. Species-level counts therefore exclude a potentially substantial fraction of taxonomically informative reads, whereas higher-rank counts include reads assigned to their descendant taxa. Counts reported at different taxonomic ranks are therefore neither directly comparable nor additive.
- Develop a method to calculate relative abundance
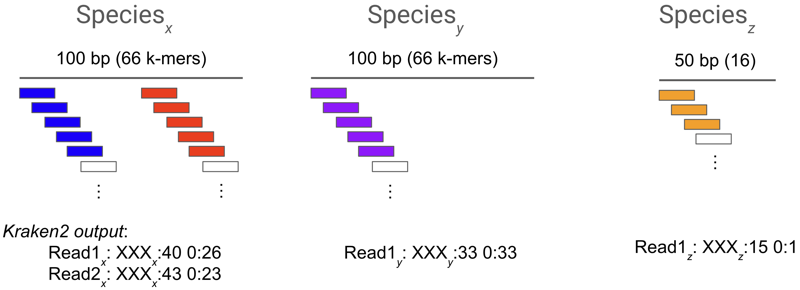
- BASEN: Base-level Abundance estimation with Species-assigned Evidence using Nanopore
- Summary: BASEN estimates species-level relative abundance by quantifying species-assigned k-mers from long-read sequencing data, normalizing by effective reference genome length (L − k + 1), and scaling across detected species to obtain genome-size–corrected relative abundances.
- Conceptual figure:
- k-mer-based read filtering (optional)
- Input: 1,237 samples
- Mice samples, N=1,206
- Donor samples, N=10
- Donor replicates, N=9
- OMM12 controls, N=12
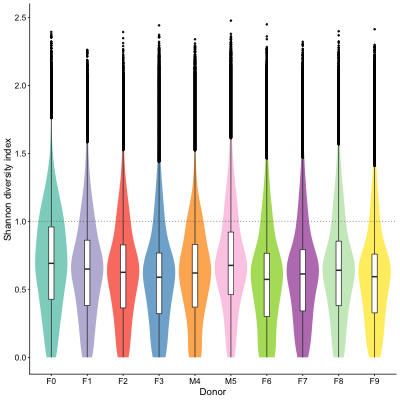
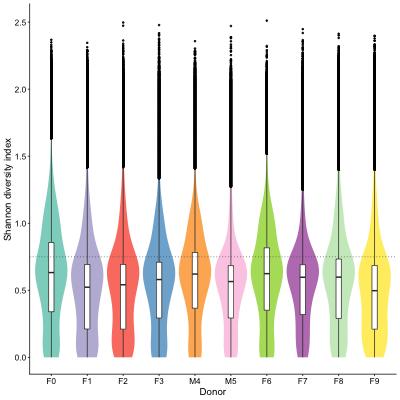
- Filter classified reads based on the proportion of unassigned k-mers and the Shannon diversity index of their Kraken2 k-mer strings (see Appendix: Classifier evaluation)
- Threshold values:
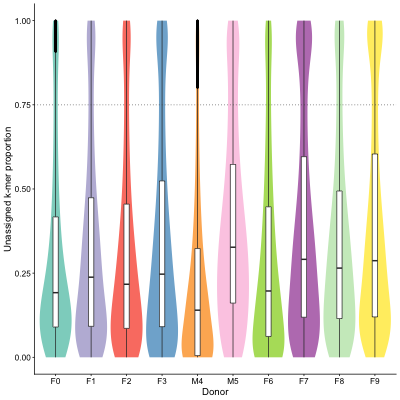
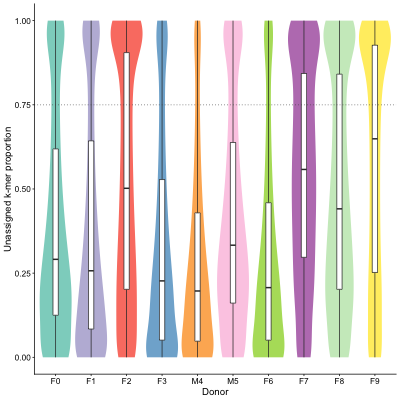
- Unassigned k-mers, proportion: >0.75
- Fewer than one in four of the read's k-mers match a genome in the database, so its assignment rests on a small minority of its sequence
- Shannon diversity index: >1.00 (Donor) and >0.75 (Mice)
- Computed with the natural logarithm over the labels in the read's Kraken2 k-mer string: each taxon ID (species or higher rank), unassigned (0) and ambiguous (A). A read whose k-mers split between a single taxon and unassigned cannot exceed ln 2 ≈ 0.69
- >0.75: the read's k-mers are spread over at least three labels, e.g. two or more taxa (competing species, or a species and higher-rank nodes) besides unassigned
- >1.00: a more lenient cut-off for the high-depth donor samples; three labels reach at most ln 3 ≈ 1.10, so only reads with a near-even split across three labels, or k-mers spread over four or more labels, are removed
- A read is excluded if either threshold is exceeded; unclassified reads are removed as well
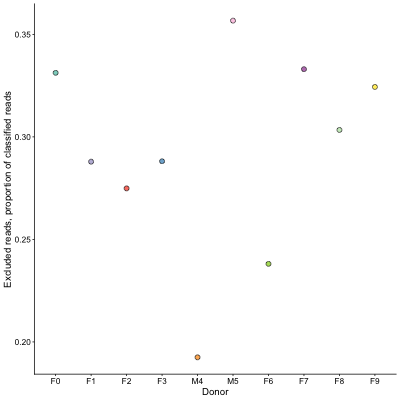
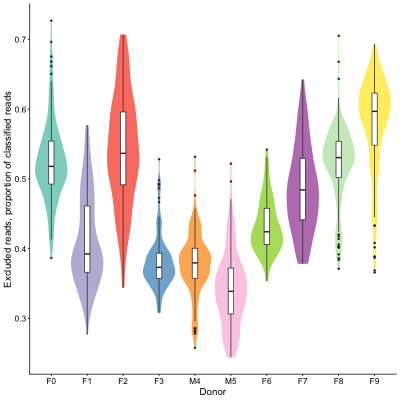
- Result: 308,643,110 classified reads → 135,558,285 excluded (43.9%) → 173,084,825 retained reads
- Excluded proportion of classified reads, median (range): donor samples 29.6% (19.2–35.7%); mice 45.3% (24.4–72.7%)
- 37 mouse samples, all ileum, retained fewer than 1,000 reads (dashed line)
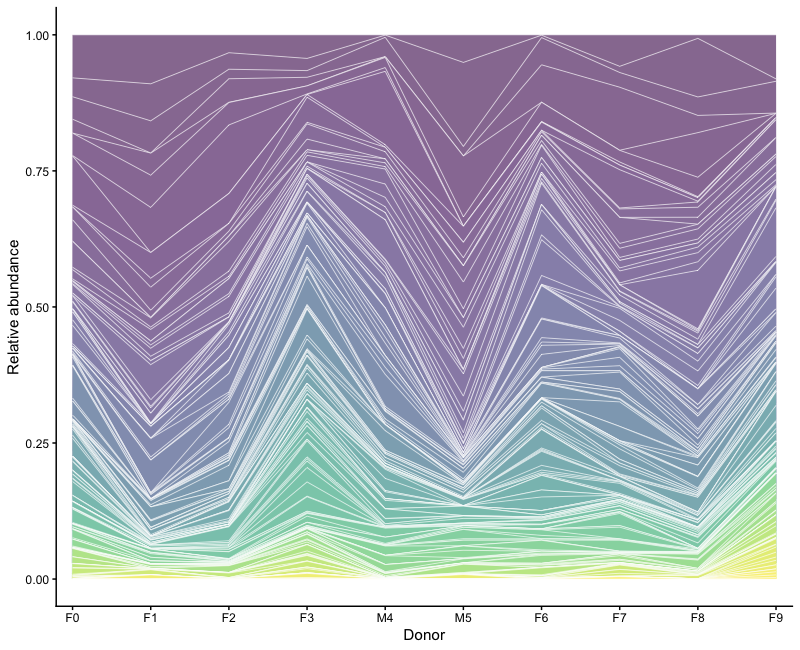
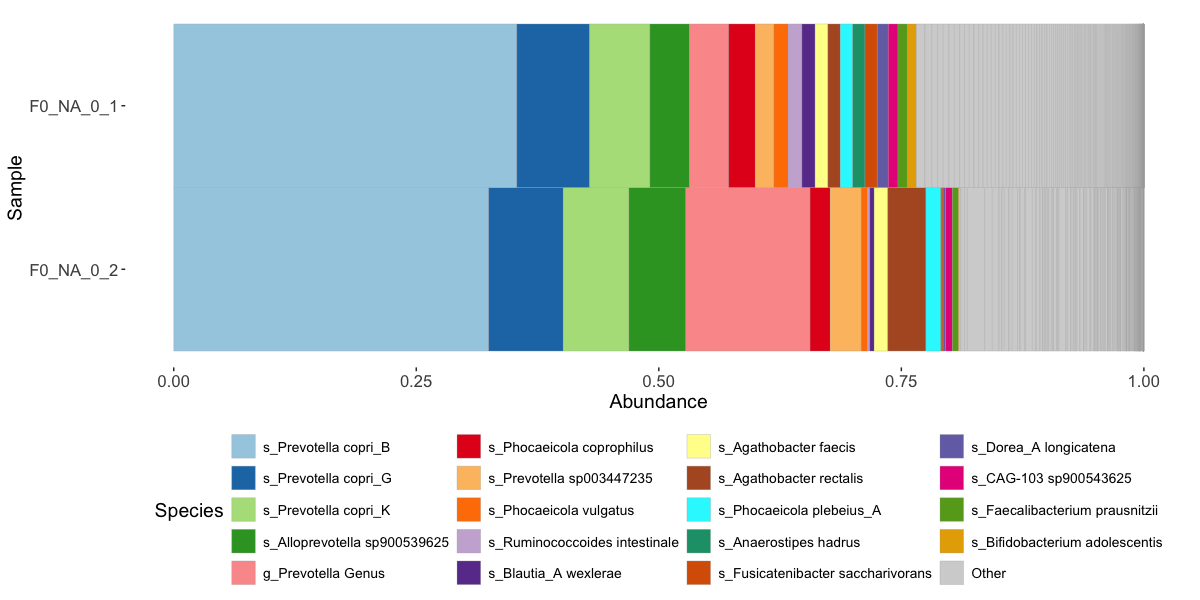
- Relative abundance of the high-depth donor samples (<donor>_NA_0_1), BASEN v1.0.0 after read filtering: Legend
- Correlation among donor samples (Pearson r of BASEN relative abundance after read filtering, N=19; samples ordered by hierarchical clustering, complete linkage on 1 − r; same-donor pairs in red):
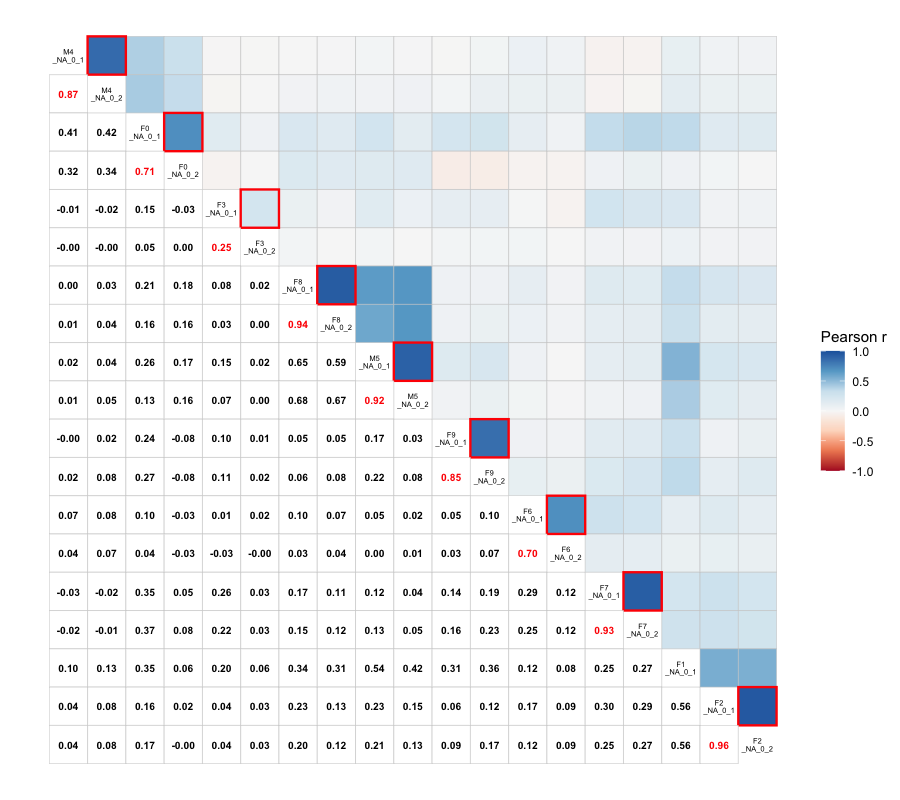
No replicate was sequenced for F1 (no F1_NA_0_2 in the study design)
| Sankey diagram (F0) | Species composition (F0) |
|---|---|
 |
 |
|
BS: the total number of species-assigned k-mers for species S GS: effective genome length of species S, L − k + 1 (L = genome length in bp, k = 35) CS: approximates the average genome coverage of species S RAS: CS / Σ Ci, where i indexes each species |
||||||||||||||||||||||||||||||||||||||||||||
| Donors | Mice | |
|---|---|---|
| Unassigned k-mers (proportion per read) |
 |
 |
| Shannon diversity index (per read) |
 |
 |
| Donors | Mice | |
|---|---|---|
| Excluded reads (proportion of classified reads) |
 |
 |
| Retained reads (log10) |
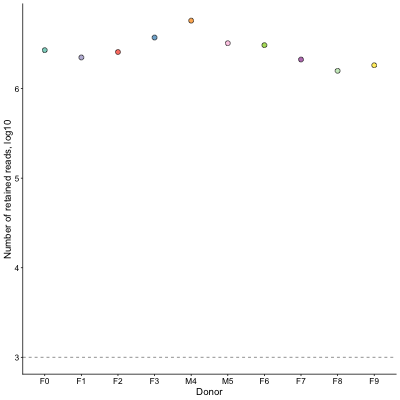 |
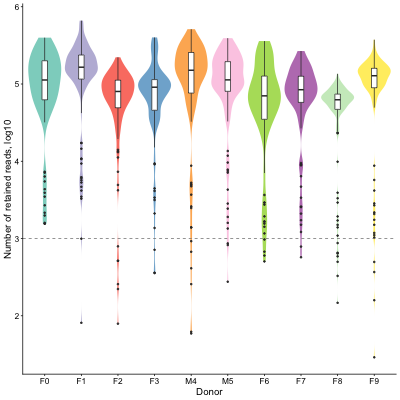 |
Appendix: Classifier evaluation
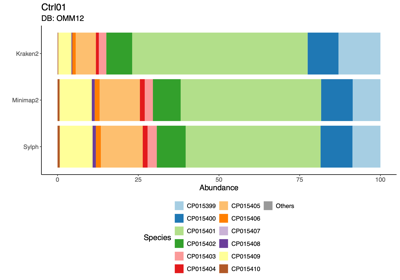
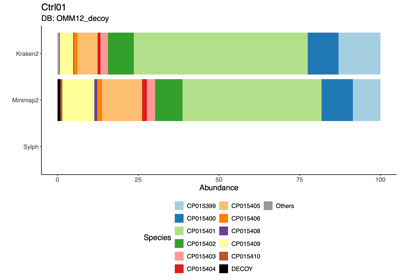
- Input: control OMM12 samples, N=12 (Ctrl01 - Ctrl12)
- Tools comparison:
- Classification results
- Note 1: MetaPhlAn 4.2, run with its pre-built database, did not classify any reads in the OMM12 samples.
- Note 2: taxonomic abundance was estimated using CoverM following read alignment with Minimap2.
- Read-level investigation 1: using the OMM12 DB
- 1:1 comparison of reads assigned to CP015399 (blue) and CP015401 (green) in the Ctrl01 sample
Minimap2+CoverM CP015399 CP015401 Total Kraken2 CP015399 C1 110,900 C2 2 110,902 CP015401 C3 1,105 C4 464,266 465,371 Total 112,005 464,268 576,273 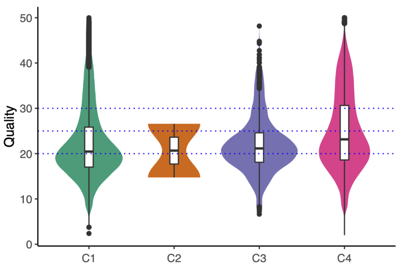
- BLAST (Basic Local Alignment Search Tool) was used to examine one of the two reads in cell 2 (C2) that were assigned to CP015399 by Kraken2 but to CP015401 by Minimap2+CoverM
- Read ID: 0ff4c7d3-1108-4a12-b7ba-5e15912d901e (length: 400 bp / quality: 26.6)
ATGGAGCCGTAAGCGGCTTTATAGGGATCGTAGGAACCGTCCAGGCCCTTGGCTTTTTTG
TAGGCCTTAAGCTGCCTGATGATGTGGTTGGCGTATTTGGGATTGTTTTCCGTCACCCAT
GCCTCAATACCGGAAGTGTCAAAGAGGAGCATGGAAGCTTTTTCCTTATTGATTTTCTGG
CAGATTGGTTCAGTCAGGTCAACAAGGCGGCTGAACATGGATTGTATGGAAGCAAAGTTC
ACCTGTGTTGAAATATTCTGTTCCCACGGTTCGATATCCAGTGGATAAGTATCCGTCATC
ACATCATCCTCATAAAAATACTCGTCGGCCAATCCGCCGAAGCTGTGTCCGAATTCGTGC
ACTACCACCGGTTTGAACATGGGGTGATGTGCCGTGGTCA - BLAST results:
1-226 bp: 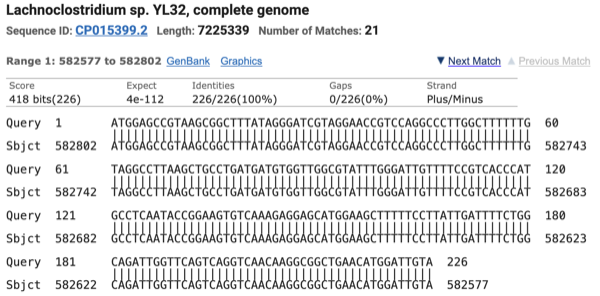
227-400 bp: 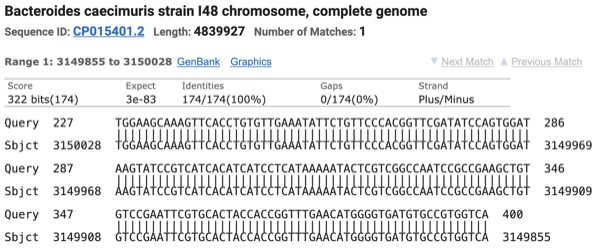
- Minimap2 is unable to align the 1–226 bp segment of the read to CP015399
- Minimap2 problem definition: Minimap2 relies on minimizers as alignment anchors but discards high-frequency k-mers, and in repetitive regions this anchor loss disrupts chaining and results in missed alignments
- Read-level investigation 2: using the DECOY DB
- One high-quality read was identified that mapped to the DECOY genome
- Read ID: 76502669-ef64-431a-97f5-81ae8693f48a (length: 255 bp / quality: 46.2)
AGCACCTTACTTTATACACATGAGCCATGATATGGGCTTGCATGCGGAAGTGGAAAAGAG
TCTTCCGGAAAATATTCACCTGGCATTCGACGGATTGGATATCTATCTTTGATTATTGGT
GAATTTTTTAGTAAAAGTTTTGTTTTCTTTGTAGAAATTATTATTTTTGCACCTAGCCGA
TAAACAGCGAATATTATGAAACTTCGTACGATAGTGAAAATAGCGATCACGTCTTCTGTT
GTACTTTTGTGCTCA - Kraken2 results:
Taxon ID Group Scientific name Hit(s) % 816 Bacteroides (genus) 71 32.1 2763022 DECOY Bacteroides sp. M10 50 22.6 1796613 OMM12 Bacteroides caecimuris strain I48 49 22.2 0 Unclassified 51 23.1 Total 222 100.0 - Proportion of unclassified reads:
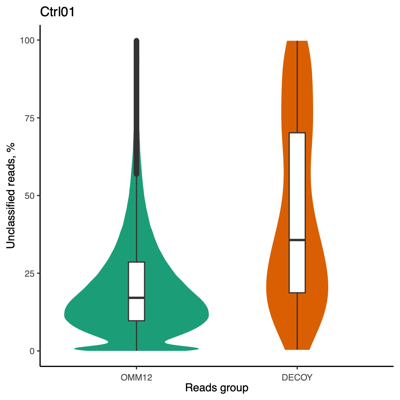
- Shannon diversity index:
Using all taxon IDs assigned to each read After removing taxon ID 0 (unclassified) from each read 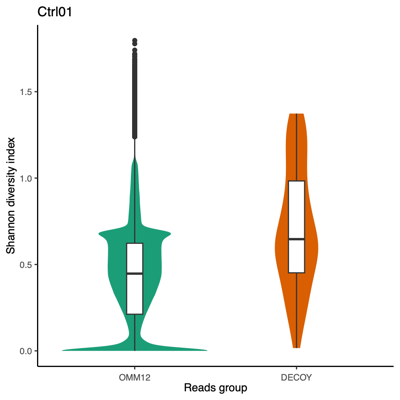
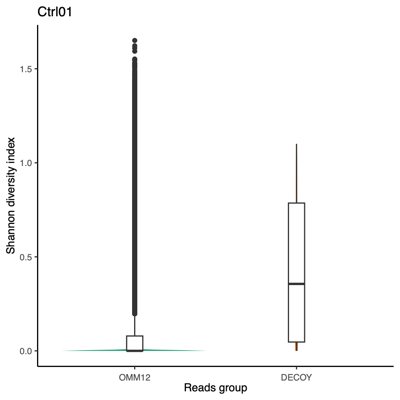
- Mini conclusion: We require a classifier that supports fully customizable databases and avoids biases introduced by sampling or repeat filtering; Kraken2 satisfies both criteria, making it the preferred tool over Minimap2, MetaPhlAn, and Sylph.
| Category | Kraken2 | Minimap2 | MetaPhlAn 4.2 | Sylph |
|---|---|---|---|---|
| Features | k-mer based | alignment-based | marker gene-based | ANI-based |
| Support long-reads? | yes | yes | yes (v4.2) | yes |
| Custom DB support? | yes | yes | no | yes |
| Strengths | high sensitivity/fast classification | high alignment accuracy | low false positives | computationally efficient |
| Limitations | k-mer ambiguity | computational demands | relies on marker genes | does not provide per-read classification |
| Output type | read-level taxonomic assignment | read-level alignments | taxonomic profile (not per-read classification) | genome-level coverage |
| DB:OMM12 | DB:DECOY |
|---|---|
 |  |